Category Archives: Project Management

Agile Cambridge 2019: piecing it together

Last week was Agile Cambridge, the annual, three-day, conference on Agile at Churchill College in Cambridge. Despite the fact that my new job role doesn’t directly involve Agile any longer, I was speaking and I wanted to go for all three days anyway, because a lot of the sessions looked interesting.

For the last couple of years, I’ve been thinking of Agile Cambridge as getting a bit samey – the same topics, often by the same speakers – and I wasn’t getting a whole load of value from it. This year was different, however. The conference had a different feel and a fresh approach, which made it very useful once again. I summarised it after the event on Twitter, thus:

End of 3 days at the 10th #agilecam. Main takeaway: Agile is now mainstream. Few talks discussing process, how to release faster, how to get user feedback. Instead, lots of team formation, the need for diverse (inc. neurodiverse) people & safe communication. We’ve come a long way

https://twitter.com/dnas2/status/1180147651448315905

In this post, I wanted to cover some of the sessions that particularly resonated.
Agile Cambridge

It starts from the team

Previous Agile conferences have tended to lump together the team as a single, homogeneous unit. This time, the role of individuals within the team and their diversity was a key topic.

  • Zara Sheldrake from ARM gave a particularly thought-provoking presentation on the subject of Neurodiversity in Agile Teams, talking about some of the ways that Agile is both good for neuro-diverse individuals (the Prime Directive, the role of Scrum Master as a shield, and pairing) and terrible (the enormous PI planning events from SAFe, open plan offices, and the language of sprinting). She discussed some ways that ARM have tried to mitigate some of these factors, both through things like mental health awareness and making the environment better suit the team.
  • Through this work, which includes features like setting team norms and personal user guides, they are trying to create a psychologically safe environment for learning. Two other sessions explored how such safe environments have been adopted in other contexts to ensure lessons are effectively learnt in life-and-death situations. In One Super Dog and her servant leader, Darren Yates from Lowland Rescue talked about how techniques for search and rescue scenarios have evolved over the last 20 years. Similarly, Jeff Foster from Redgate explored Why planes don’t crash, again about how the aviation industry goes to very substantial lengths to ensure they fully understand root causes for any incidents, so that flying is made safer. It really made some of our retrospectives seem quite superficial.

It’s always communication…

  • Of course, all of this ultimately comes down to the most difficult problem in software development: communication. Nick Maidment, now at ARM, previously Metail, explored some of the challenges Metail had faced and overcome as they moved from a mainly onsite team to a mainly remote one. As you might expect, neither extreme proved particularly problematic, but The Space Inbetween, where only a couple people are remote, is where the difficulties lie.
  • One of the few talks to directly relate communication to processes was Your bugs aren’t special by Emily Tate. The challenge is the perennial one that ‘little things’ often get done on the sides of the prioritised work. In one case cited, the ‘little things’ were taking up to 30% of the iteration time. The thing I found most interesting was framing this as a communication breakdown, that different stakeholders aren’t adequately talking about their competing priorities.
  • Related to both the psychological safety and communication themes, Redgate’s Chris Smith ran a workshop on Crucial Conversations. He explored some of the theory from The Chimp Paradox to explain how we can help get our ‘chimp brains’ under control at work, and how to accept it when we, or other team members, have chimp responses.

How to get change

  • One of the bases of what Chris was talking about is that you can only change yourself, not others. You’re much more likely to be successful by opening your own mind than trying to convince other people of your opinion. This was also a message that came across in Linda Rising’s second keynote of the conference on Moral Foundation Theory. Her argument was that we should aim to listen people into agreeing with us, and we can do that by examining issues from the opposing moral standpoint. For liberals, we tend to argue about care and fairness, while conservatives tend to focus on loyalty, authority and sanctity, so listen for their arguments from their moral foundations. Linda’s other key message in this talk was that correcting people with data tends to lead to them holding their view more firmly. This is because we’re evolved to take quick decisions and justify them later. It’s much more effective if we tell stories around our ideas like a press secretary, rather than as a judge spurting facts.
  • The different points of view in a team, and the challenges arising from them, was also the topic of Linda Rising’s first keynote of the conference, Who do you trust? Beware of your brain. She used the example of the Robbers Cave Experiment to show how we are keen to divide ourselves into them/us tribes, even when there is no difference between the groups, and how the tribes were only unified when there was a significant, real-life problem, to solve through joint teamwork. This is a lesson that software team leaders can learn from.
  • Selena Delesie’s keynote The Soul of Agile, picked up on some of these points. Her fundamental message was that we get the best from our teams at the intersection of three things: An open mind (curiosity, to have power with an individual, not over them), an open heart (compassion, focusing on the individual) and an open will (reducing fear and increasing courage in the team by being willing to release the need to control individuals and releasing the need to have future plans). Notice the focus on the individual here – you may need to take different approaches for different people.

Diversity in background

  • If all of the above focus on individuals seems hard, it’s worth it because of what different skill sets bring to the team. In the keynote The Death of the Liberal Arts, Ashley Hunsberger argued that there is a need for liberal arts students in development teams, because understanding what to analyse, the context of data , writing (communication) and giving feedback are all transferable skills that are gained in essay writing in literary criticism. The ability to juxtapose having a big picture view while also focusing on details is (literally) a feature of art criticism. So why do we often insist on Computer Science degrees in our job advertisements? The other thing that liberal arts students can bring is the consideration of ethics. The need for ethical programming is becoming increasingly visible with the likes of Cambridge Analytica news stories, and so asking ‘How can what I’m building be used to hurt somebody?’ is a useful thing to consider.
  • The other regard in which we might want to consider ethics more is asking ‘How does your product end?’. In the final keynote of the conference, Ends – The lost narrative of consumerism, Joe Macleod promoted thinking of the off-boarding journey for your product as much as you think about the on-boarding journey. Considering what happens to a product at the end of life, whether it’s software and there’s a hard user experience to let go, or hardware that needs recycling in an easy way, off-boarding can make business sense in increasing loyalty. (Incidentally, in our field of academic publishing, the whole industry has mechanisms to ensure content lives on after a publisher has ceased to exist.)

So what am I taking back to work?

First off, I haven’t covered a couple of the useful sessions in this post so far, because they didn’t quite fit the narrative flow. Given my recent change in job title, however, I found Stefan Tilkov’s session on Agile Architecture and Innovation particularly useful, and I’m certainly talking to my colleagues about his ideas. I especially liked his proposed Architecture Manifesto on the basis of the Agile Manifesto as a way of explaining what we are trying to do:

– Conscious trade-offs over emerging architecture
– Documented rationale over quick ad-hoc decisions
– Sustained changeability over easy initial development
– Design for replacement over design for re-use
– Simplicity over fast delivery

Stefan Tilkov

Beyond this, the other things I want to do include:

  • Considering the needs of individuals more than thinking of Agile as a one-size-fits-all thing that the team agree and compromise on. I may well promote Zara’s talk a bit within the company.
  • Trying to change the P1 process we have at work for retrospectives so they are more deep and get to better root causes. Of course we aren’t the airline industry, but thinking about some of their detailed analyses is something we could do to improve.
  • I’m going to read The Chimp Paradox so I can look out for ‘chimp responses’ in individuals and account for them better.
  • Think more about working with remote colleagues as we are in that ‘space inbetween’ of having just a handful of remote workers.
My first six months in a new role

The spectacular view of the London skyline from my office roof

As those of you who know may will recall, I was made redundant from my job as a Scrum Master at Redgate back at the end of May 2016.

Luckily, I wasn’t out of work for too long and since July I’ve been working at a major multinational ecommerce player in the travel and tourism sector (very boring company rules on publicity mean I’m not allowed to name it in blog posts but that doesn’t matter)…

The team I’m in is a backend data team, looking after a number of the main company data sets. As such, our ‘customers’ are the business analysts and finance people who use that data in their reporting.

The wide variety of the sorts of data we handle means that the team is split into sub-teams, handling everything from the basic booking data to feeds of bookings with commission payable on them, and from the data relating to A/B testing on the website to the OLAP cube that’s used by the financial people for reporting up to the CEO.

New challenges

This role has brought a number of new challenges for me so far, which stem just from the nature of the job:

  • Our customers do queries in the databases we provide, so ‘user stories’ are often no more interesting than ‘provide this data in a new column in this table’. Sure, we can explain the business value but there’s no concern about usability and, with the stakeholders in the building, there’s often no interpretation required about what they are actually trying to achieve.
  • Being a publicly-listed company, there are significant overheads from security and auditing concerns. As much as I might like the team to fix their own problems, they don’t have access to a lots of the production systems they deal with in order to enforce separation.
  • Since I joined, it has become a global team, with people in both London and Bellevue (Seattle). In an attempt to avoid siloed knowledge, we have refrained from having some work done in the US and other work in the UK – the work is shared between the two locations, even though this creates a bigger need for communication.
  • Like any team handling backend systems, work is regularly interrupted by critical production issues that can’t wait. This is made more difficult by the fact that we’re handling very big data where processing times are measured in hours if not days. Any delay in fixing a problem can have significant impact on downstream systems and, ultimately, the ability of people to do their jobs.
  • The sub-teams work with a Technical Product Manager, rather than a Product Owner as defined in Scrum. The difference is that the TPM owns not only prioritisation but also provides a lot of detail (sometime too much) on the implementation side.

The first few weeks

As is always recommended, I spent my first few weeks watching how things were working and understanding what I should concentrate on trying to assist with first, resulting in a set of objectives for the first few months, such as:

  • Restarting retrospectives
  • Getting epic-based swimlanes on the Scrum board

    (Individuals had their own work in their own swimlane, which was clearly hindering the notion of working as a team when they each had diverse work to do, and would make migrating towards a Kanban approach in the future problematic)
  • Stopping the useless sprint demo sessions the team was having

    (Stakeholders never attended them and so it was just a ritual for the developers to show each other what they had done in deep technical detail)
  • Supporting the existing initiative to have dashboards showing what data was available and how up-to-date it is

    (The team was working in a very reactive way and often wasn’t aware of problems until our end-users had spotted them.)
  • Improving communication with stakeholders through introducing regular A3 Reporting on high-profile / larger projects

There were two much bigger things on my plate, though, which I’ve spent the bulk of the last few months on: getting the Bellevue team set up and developing the sub-team that’s responsible for the OLAP Cube.

Creating a remote team

This was actually a process that was underway around the time I started. My line manager had just moved to Washington State from London to found the team there, and moving the two Indian developers to the US was just the first step. Between October and December 2016, we had two more developers join in America too.

What fell to me was the practicalities of making this work, when the majority of the developers were still in London, as were all the stakeholders. When it had just been two developers in India, standups could still happen in the morning in London, which was early afternoon in India. The switch to the Seattle area now meant that it was the middle of the night there during the morning in the UK. I didn’t want to move the London standup to the late afternoon, as that would rather defeat the object in my opinion, so we introduced an additional catch-up call at 4pm UK (8am Pacific) to ensure work is kept in sync. To complete the cycle, the team in Washington State leave a message in HipChat at the end of their day, which we can pick up the following morning.

This sort of practicality, and the need for planning and retrospectives to be held at the end of the London day, is easy to resolve, while not ideal. It has certainly led to me having a very odd-shaped day, where I’m relatively free during the middle of the day, and very busy with successions of meetings at the end. The most unexpected issue we’ve faced is a perception among stakeholders that quality has reduced: If things broke overnight London time, they were used to it being resolved by the Indian developers before the stakeholders arrived at 9am UK. That no longer happens, of course.

The biggest issue however, predictably, is communication. As I’ve said, we’re trying to avoid silos by having work shared between people in London and Bellevue, rather than allocating different tasks to each place, but that means getting communication right is incredibly important and complex. Add into the mix the need for the TPM in London to answer the majority of questions, and you’ll understand the difficulties when there’s only 90 minutes of time overlapping between the two offices per day. We’ve already had a couple issues where the Bellevue team-members weren’t quite aligned on the project goals, and a near miss where work was almost duplicated between two people in different places.

Cube team

When I started, the Cube team was in a really bad place. Unlike the rest of the wider team, they’d been pretty much ignored and didn’t really have any process at all – neither Waterfall, nor a form of Agile. They had lots of disjointed, small tasks with no real stories tying them together, and a technical debt backlog kept separately from the product backlog. We’ve had a couple of stories that were aborted during development, because it became clear that the value wasn’t as expected. Above all, however, the people in the team didn’t get along. There was a lead developer, who had the technical skills but struggled with people skills. He was also the original (only) team member. Subsequently, another, more personable, team member had joined and had been made team lead before I started, which naturally caused some tension between him and the original developer. And, most recently, a new junior developer had come into the mix, and was naturally caught in the tensions between the two, which I think was partly a cause of him having little confidence.

What a dream scenario! I believe strongly that people problems can be fixed if caught early enough. I took them through a ‘5 Dysfunctions of a team’ training session over several weeks and we managed to resolve many of the interpersonal conflicts. Simultaneously, I put some gentle pressure on the TPM to improve the roadmap and started setting them up with a basic sprint cadence and teaching them Scrum. This doesn’t come overnight, of course, and they’ve struggled to complete their sprint commitments but by showing them data on what their velocity is, we’re getting nearer.

The plan from now on

The next few months are also going to be very busy. A couple of new major projects is almost certainly going to result in having to adjust the team structure slightly. But beyond that, there are a number of more fundamental things to fix:

  • I want to get the OLAP Cube sub-team working closer with the other sub-teams that they are dependent on. This isn’t helped by them having a different TPM and a different roadmap.
  • I’m introducing a more thorough kickoff process for larger pieces of work, moving from a model where one or two people do a spike and produce reams of spike documentation, to one where the whole team is involved hearing directly from the business what the requirements are.
  • Starting to experiment with introducing BDD as a way of having conversations about the requirements.
  • Set the expectation that Sprints should end with a tangible thing that can be demoed. At the moment, everything is still very waterfall. I see creating regular, tangible, value as the key to getting stakeholders back into demo sessions.
  • Starting to introduce Kanban in the sub-team that has most production issues to deal with.

Exciting times ahead… 

Direction, momentum and oil: Why software development teams are like bikes

I haven’t posted for a while on what I’ve been up to at work and there’s a good reason for that: the team I’ve been working with was pretty dysfunctional twelve months ago and I’ve been spending the last year trying to turn them around. In this post, I’ll describe that journey and why I’ve concluded that software development teams are like bicycles.

Context

I was first asked to spend a couple weeks in April 2015 working with Redgate’s SQL Monitor team as an external observer, finding out why their Project Manager was struggling and why the team was perceived as delivering slowly. In this environment, some of the team were even starting to leave the company…

A bit of background: the SQL Monitor project had been stopped for just over a year after the release of version 4 in January 2014. In the intervening time, no work had happened on the product, and the original team had disbanded. Many had gone off to do other things. In the meantime, revenue had continued to increase and so, in early 2015, the company decided to form a new team to continue that growth. The new ‘team’ (a mix of different people that had been cobbled together, most of whom had no experience on SQL Monitor) would work on one feature in order to get used to the codebase, while the company decided on what the further roadmap looked like. That didn’t sound like a team set up for success.

In my favour was the fact that the team knew they had a problem and so were prepared to work with me to address it. We didn’t have much time, though: the following week, two newly-hired developers were set to join them and we needed to make their introduction as good as possible. So, the usual advice that a Project Manager / Agile Coach should just start by observing the team went out the window. I had to act fast.

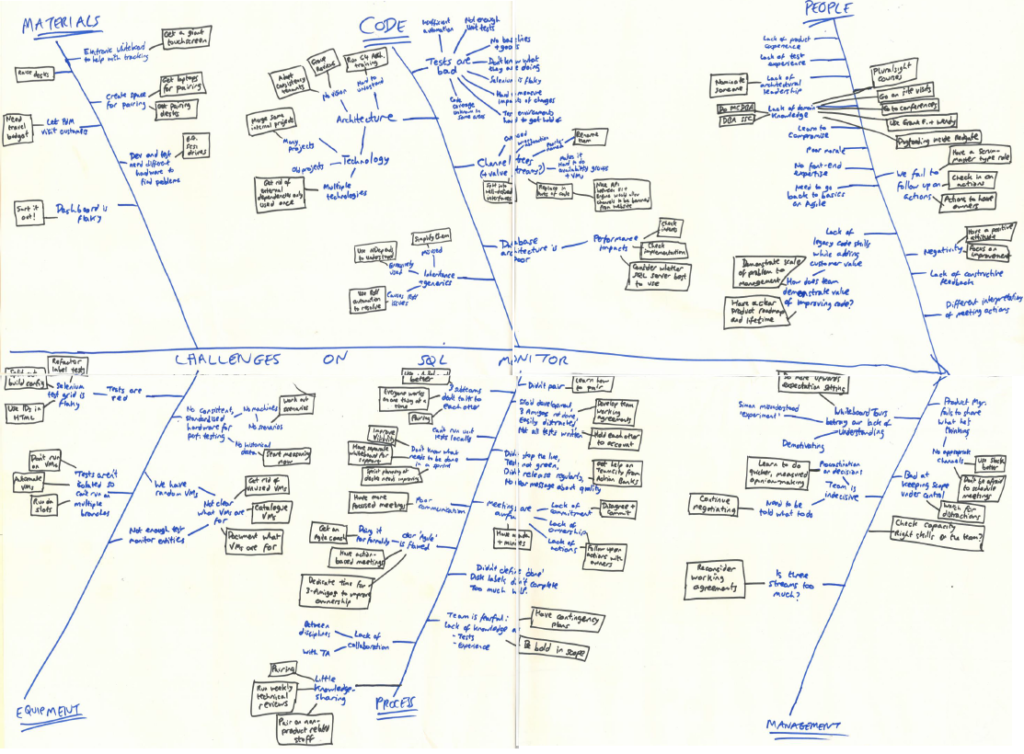
I started by organising a retrospective with the team to investigate their various problems. This was a fairly painful session, which I facilitated, using a fishbone diagram technique:

Fishbone diagram

As expected, there were a number of really fundamental issues here, mainly with the state of the code, but feedback was that it was quite cathartic for the team to see them written down in one place.

To summarize, this was a pretty bad situation: the team had no goals, no deadlines and were struggling to do valuable work. In other words, they had no direction or momentum and the bicycle chain wasn’t even allowing the different parts to work in concert.

Giving a direction

During the same week as that retrospective, I sat down with the Product Manager and got his opinion on commercial direction. It turned out he had a presentation, that had already been presented to other managers, with his idea of a roadmap. It was a well-thought through plan; it’s just that the dev team hadn’t yet seen it. That was another easy fix – I got the Product Manager to give the presentation to the developers and let them challenge the rationale. With this approved, he could then go away to create a 5-year roadmap – rather unusual at Redgate but vital for giving the developers a sense of confidence that the project wasn’t about to be stopped for another year again.

The outcome of the Product Manager’s work was that there were two obvious big features to be done soon – support for Active Directory and support for SQL Server Availability Groups. Both of these were features which competitors had implemented already, and were actively costing us sales. The work felt likely to take a few months, it was mid-April 2015 and there was a big tradeshow, SQL PASS 2015, coming up in October. The way forward seemed clear. I’d re-focus the whole team on those two features and temporarily shut down the other distractions the small team was simultaneously trying to work on (mainly support escalations and code quality improvements). Stopping distractions, and especially support escalations, isn’t easy, and can’t be a long-term solution, but in some cases I’ve found it to be a very useful tool. If you have the right conversations, even the support personnel in the firing line from customers can be brought into the idea.

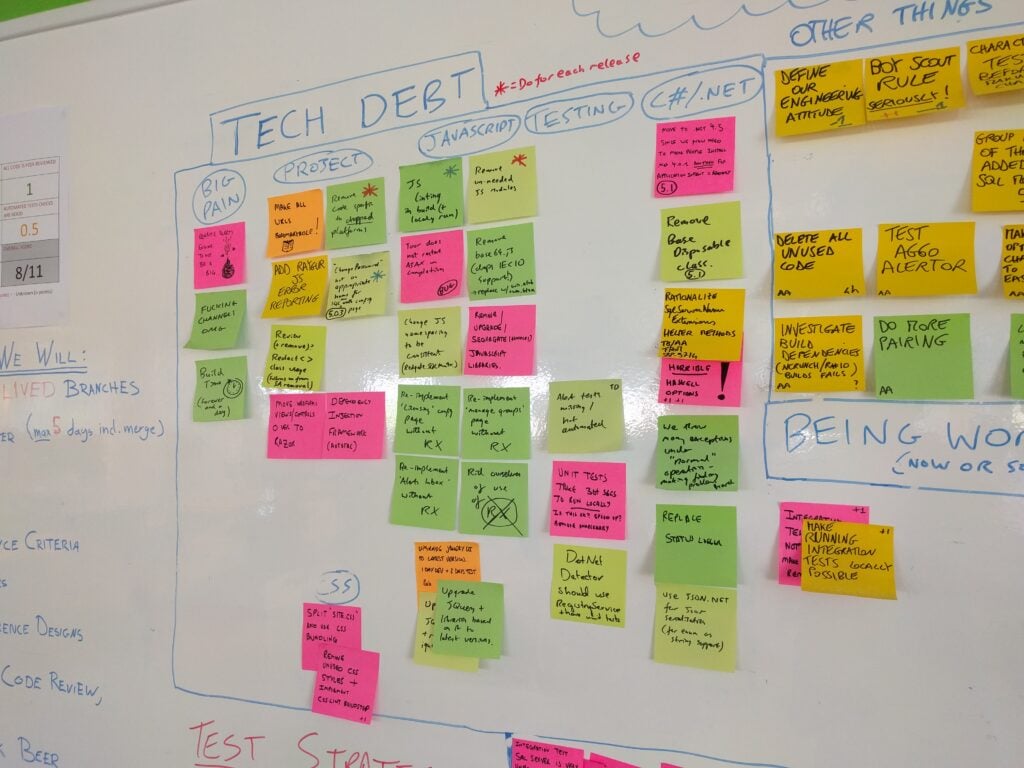
Some people may question the idea of stopping the work to address code quality but the fact is that random pieces of improvement work were being picked up by developers with little planning or sense of what the most important work to do was. Instead, I asked the team to just write down the known technical debt on Post-Its as they were discovered, and stick them to the wall. Together with the actions from the fishbone retrospective, that became a visible reminder of how much debt needed paying back and, in due course, would form a backlog of improvement work to be addressed.

The tech debt wall

Of course, things never are straight-forward. Just as I was starting to get this running, a critical security vulnerability was found in SQL Monitor 4.1. The plan had to be put on hold while SQL Monitor 4.2 was released, and the fix was also backported to previous versions of SQL Monitor.

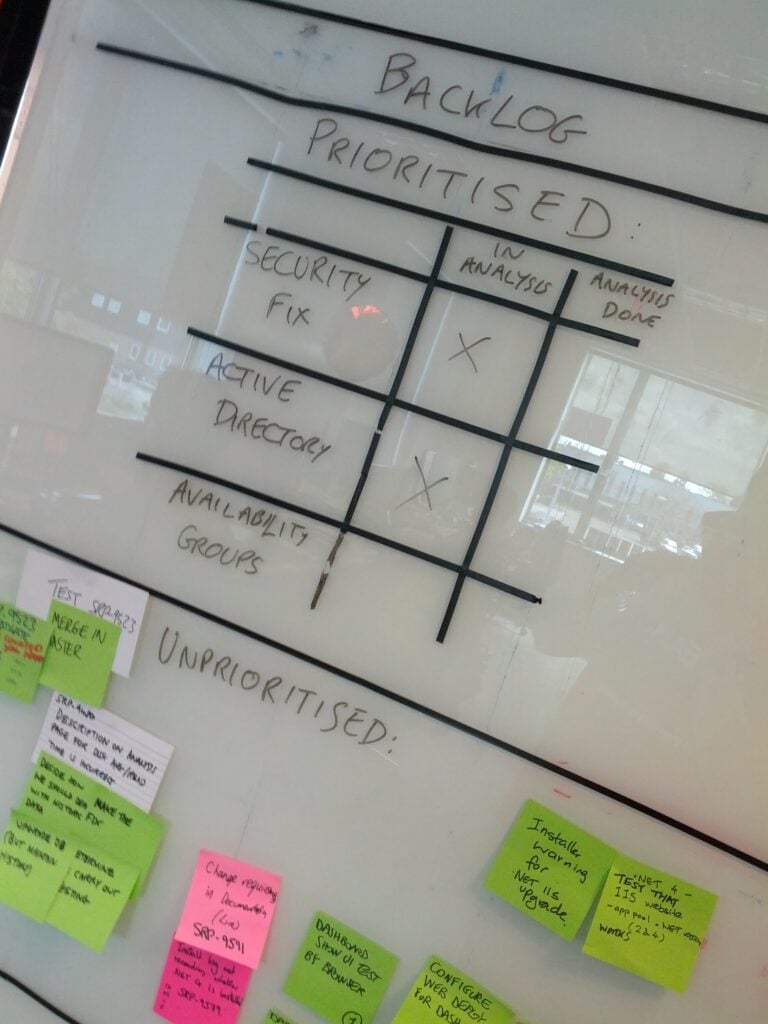
Explicitly showing what work is prioritised and what is to be done later on

 There – my job was done. The team had a road to follow and, a month or so after joining them, I could leave them in the hands of their normal Project Manager to continue the work…

Speeding up

At the end of July, I returned from a holiday to discover that the existing Project Manager had decided that he no longer felt confident in managing the project. It was a very brave decision to make, and meant that I was catapulted back into the SQL Monitor team again – this time as full-time Project Manager.

My job, though, was fairly obvious by now: keeping the team focused on delivering in time for SQL PASS 2015. This mainly consisted in keeping a fairly tight reign on the team’s approach to sprint planning and capacity planning, at least at first. This ensured also that there was no time available for some of the quality improvement work the team wanted to do, a deliberate choice by me to keep the sense of purpose. Over time, we found a way to handle support escalations once again, and I eventually released the brakes I’d artificially applied to guard against scope creep/changes.

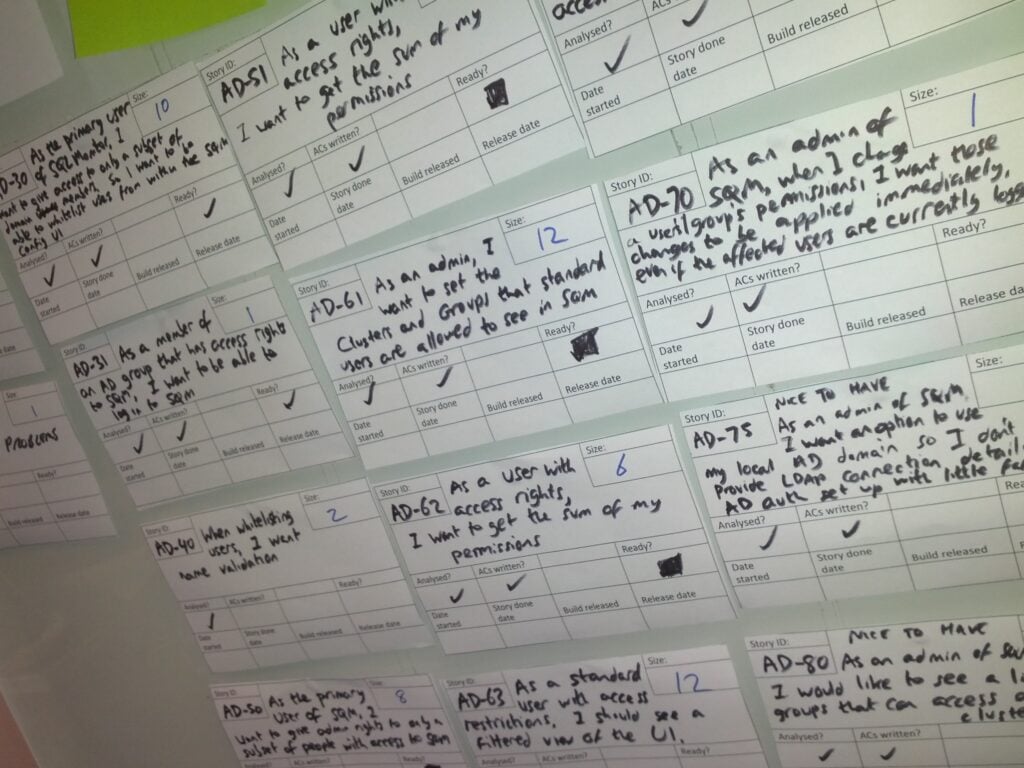
To bring the team back on track, we enforced user stories, estimation and acceptance criteria.

We did it – SQL Monitor 5.0 was released just before the tradeshow, on time and without significant amounts of cutting things from the planned scope.

Through the work on version 5.0 we’d deliberately not released frequently: releasing was hard and required extensive manual testing because the automated tests were unreliable or covered the wrong things. Given the length of time since the last major release, and the team’s lack of knowledge, trying to release regularly could have caused too many derailments.

So, having reached SQL PASS 2015 intact, it was time to set the next challenge for the team: work out how to release frequently. For the major release, the testers had done an extensive risk-based analysis on the major areas of the product they’d need to test. They now used that as a first step to working out what minimal testing would be required. Meanwhile, the developers set to work getting rid of those unreliable automated tests, replacing them where possible, and changing our branching strategy so we’d always be in a position to release.

And that backlog of improvements to the code we needed to make? I got buy-in from the stakeholders so that we could keep our promise. We gave the team two months, without pressure to deliver features, to start working their way through the backlog.

By the start of 2016, we could release every sprint and some of the most egregious code problems were gone. The bike had gained its own momentum.

Providing the oil

Naturally, it hasn’t all been completely plain-sailing. The release notes from the start of 2016 show that there were several bugs and regressions that we introduced as we moved to the new model. For the customers who were affected, we’re sorry. But the fact that the SQL Monitor code, while still far from perfect, is improved, better understood by the team and able to be released quickly means that we’re in a much better position to do some great work in 2016 than we were last year.

By now it should be clear what my role in all this was. The team is pretty much unchanged. The way they work is only slightly different. The developers, testers and designers are still the gears, chain and wheels of the bike. Without them, we wouldn’t have a bike at all. My job was one of lubrication: providing the oil and a bit of direction and momentum to ensure they could go on their journey. It was done through adding brakes and stabilisers where necessary to prevent them from going too far off-course in the early days, then empowering the individuals by giving them the time and space to address the problems they wanted to fix and by protecting them from the mud of management that might have interfered with the way they were working.

Postscript

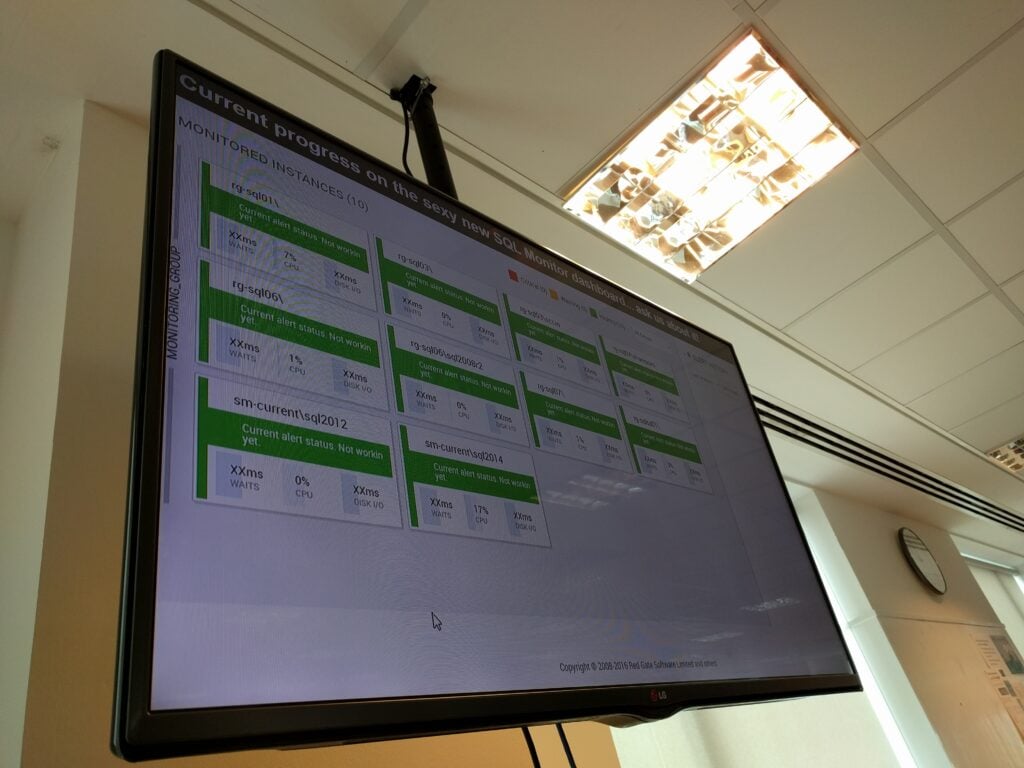
The team’s now working on some really exciting stuff ahead of SQL PASS 2016, including a very impressive new dashboard which is nearing completion.

As for myself, my mentor, Simon Cromarty once told me that the aim of any project manager should be to make themselves redundant: You succeed when the team doesn’t need you any more. So, in a rather perverse way, it should be good news that I stand to be made redundant from Redgate in the coming weeks. If you need someone to help oil your bicycle,  let me know…

What is technical debt?

This article is my own synthesis of ideas presented at Lean Agile Scotland in September 2014 by Dan North, Jabe Bloom and Torbjörn Gyllebring, with some of my own embellishments. Any misunderstanding of their points is mine! I’ve linked to their original talks at the foot of this post.

Conway’s Law says that the design of our system will be rooted in the design of our organisation.

So, we can never design a system from scratch: some of the design will have already started before we start designing.

This isn’t necessarily a problem, however: indeed, we should embrace it, because organisations suck if they don’t have the right APIs and other architectural borders in place between where teams are (that’s when teams start to get bureaucratic layers preventing their work from proceeding as their pace.) We should take time to get this right, and this is why having micro-services to do communication between teams is a good idea.

However much we work on this, however, we will face problems in the code we write, many of which will relate to the architecture. We can either chose to fix the symptom (via a quick fix) or to fix the underlying problem (which is generally more time-consuming). Quick fixes aren’t necessarily bad when applied in conjunction with a longer-term fix but remember they are akin to painkillers, and you can’t take painkillers indefinitely.

Quick fixes often take the form of a mandated structure: we might add too much or too little process, a particular build system, an architectural design ‘recommendation’, a decision on a particular source control system or IDE, or similar. As managers, we should be especially careful with such quick fixes. We are aiming to apply a ‘Goldilocks’ amount of constraint on our teams: too constrained and development will stop because the people can’t do their job; too little constraint and there will be too many options to do the right thing. The right amount is a strategy that’s clear enough to give us a task for today and a constrained set of options for the future. That strategy is actually a conversation – top-down constraints from management, and bottom-up information and designs from the development teams.

Partly because of the difficulty of identifying the ‘Goldilocks amount’ without information from the team (which presupposes time taken to do investigation), quick fixes generally tend to exhibit more unintended consequences than fixes that correct the underlying problem.

In a Cynefin sense, rather than taking time to analyse a problem as demanded by Complicated scenarios, our quick fix has made matters worse by creating a Complex relationship. The side effects can’t be foreseen, but become apparent in retrospect. Worse still, the quick fix may fail to address the root cause of the problem, and so we may get a positive feedback loop causing problems to increase as a result of our solutions.

This is technical debt, because the system starts constraining what we can do.

Cynefin tells us we should monitor for this positive feedback and, when we sense it, take time to respond to it, possibly by rolling back the change and trying a different approach.

To check for technical debt, therefore, we should periodically take time to ensure that our system isn’t constraining us. We can do this, for example, by ensuring our tools haven’t become our masters by checking that we can still build our products using a single command line (without complex CI systems) and that refactoring can be done in Notepad (without Resharper).

Original videos:

Understanding a feature through 3-amigos

The last project I ran here at Red Gate was on SQL Compare / Data Compare 11 project. SQL Compare is a superficially simple product designed, as it’s name suggests, to compare Microsoft SQL database schemas. Its cousin, SQL Data Compare compares the data in the tables.

Like the product itself, the Compare 11 project had a superficially simple goal: add support for the new features in SQL Server 2014. Easy, right? It turns out, not so much…

The largest new feature is Memory-Optimized Tables (MOTs): the ability to keep data in memory so you get significant performance improvements through reduced disk-access. But as you dig into what MOTs can and can’t do, you realise that you’ll need a lot of special-cases in the code to deal with the limitations. The details of those limitations is well outside the scope of this post, but one of my colleagues Michelle Taylor has written a useful post on our company blog for those who want to know more.

When the team came to start work on this story, which was before the release of SQL Server, some of the limitations weren’t immediately apparent. This led me (as project manager) to a false sense of security, and so I was far too lax on getting the user stories and acceptance criteria defined in detail. The lack of knowledge this created in the team caused the feature to become massively under-estimated: just 50 task-points (at their velocity, each task-point turned out to be just over an hour of real work).

The first tasks related to this story went on the Scrum board early in the project: ‘Add property to CreateOrAlterTable’, ‘Add property to DatabaseObjectsTable’, ‘Update DatabaseObjectsTable.Equals()’. You see what’s missing? We had dived straight into implementation with no form of planning first. That first sprint was estimated as 15 points. By the time we got to the end of it, we had uncovered quite how unexpectedly complex this feature was likely to become. We were nowhere near 30% (15 out of 50 points) complete on the feature. We carried some of the tasks forward to the following Sprint, however, trying to convince ourselves that we’d crack it soon. Before I knew it, we’d spent nearly a month on this feature, continually uncovering more and more complexity, and morale on the team was starting to become impacted.

Even then, my monthly project A3 report excessively optimistically promised that we’re complete both Inline Indexes (another 2014 feature) and Memory-Optimised Tables in the next four weeks.

It was time to pull the Andon cord.

Luckily, this also coincided with a slight change to business focus. The team was being asked to ship SQL Compare 10.7, giving support for connecting to SQL Server 2014 (but not the new features) to ship with the final release of SQL Server 2014.

Whilst this was a massive disruption to the team, it did give us some breathing space to find out more about MOTs before we had to work on them again.

By the time we were ready to start work on MOTs again, the Product Owner had defined the Acceptance Criteria in more detail. There were a series of tasks, themselves totalling 42 task-points in estimates, which centred on reviewing these ACs and making sure they made sense. This worked OK, and put us in a much better place, but with a large team, the meetings didn’t really work.

At this point, one of my colleagues pointed me to the idea of a 3-amigos meeting. I’d actually tried this once before on a different project, and I found myself wondering why I hadn’t tried this earlier on the MOTs work. The idea is to have three people (specifically the Product Owner, a Developer, and a Tester) in a room together, defining how the feature should work for users, in the code, and in test cases respectively. There’s a good write up of the meeting on the Scrum Alliance website; the only difference for us being that the Product Owner also doubled in the BA role for us. Although it felt slightly more waterfall than we were used to, the output from the meeting was a set of really well defined, clear Acceptance Criteria and a good common understanding of what MOTs involved, that was ready for sharing across the team.

The team re-estimated the work, and came up with an estimate of 250 points. In the end, it took 337 – still rather more than 250, but also far more than the original 50 points planned!

This process worked so well that we adopted the same meeting for other features in SQL Server 2014, rotating the role of the amigos through the dev team. As long as the communication about what was discussed is good immediately after the meeting, everyone became brought into the idea of 3-amigos, and ensured that the chaotic start to MOTs wasn’t repeated during the rest of the project.

A year of whiteboard evolution

My colleague, Simon (aka The Agile Pirate), has written a post on his blog about how our team’s Scrum Board has evolved over the past year. Until I Simon’s summary, I wasn’t quite concious of how much we have achieved since January.

It’s probably worth supplementing Simon’s post with something about the aim of the ‘bigger picture’ sections of the board, which I was primarily responsible for instigating. One of the problems we had with the standard current-sprint scrum board is that the team wasn’t always aware of where they were in the bigger scheme of things. This meant that there seemed to be a tendency to get bogged-down on a particular feature or story, and lose sight of how it fitted with the rest of the release. The was a particular problem on the ANTS Performance Profiler 8.0 project, which was a longer duration than many of our normal projects. Ensuring we had a visible record of what’s coming in future sprints meant that the team kept this focus better.

The Project Plan sheet that I had developed by the October photograph is an attempt to clarify our goals and objectives a lot better, helping the dev team to take informed decisions about the value of any particular task. I’ll blog about the rationale behind the design of that page another time.

Read A Year of Whiteboard Evolution on The Agile Pirate.


Reflections from Agile Cambridge 2013: Day 3

[This post continues from Reflections from Agile Cambridge: Day 2]

Real Options in the real world (Chris Matts)

This was a fascinating keynote investigating how we can consider the options we face in project management as being Options in the financial sense: they expire, they have a value and we should avoid committing to them too early.

Being able to take options requires you to have slack time in which to take them: Chris used the analogy of the lion who is an effective predator because he spends most of his time asleep in a tree. Taking options also involves considering how we will roll back a decision. There was a warning against using mathematical probability to decide what is unlikely to happen, because human beings tend to be too optimistic when calculating risk. Instead, we should aim to have a plan for what we will do if the risk occurs.

The other strand in this talk was around staff liquidity. All too often, we allocate people to tasks because they are the expert in that field. This just creates silos and dependencies on individuals. Instead, we should aim to keep the experts for training other people or for responding quickly to unforeseen circumstances.

The art of systemic feedback (Marcin Floryan)

Marcin’s talk considered the best ways of collating feedback on what we do. The main thing I learnt was about the relationship between the Cynefin model and the appropriate feedback loop to use. Marcin demonstrated how Complex problems should be considered using the OODA loop, while PDCA is more suited to Complicated problems. One area in which I wasn’t so happy was the idea that Simple problems don’t require feedback because there are established practices. Surely those practices themselves have room for improvement?

It’s not your fault – why targets don’t work (Francis Fish)

This talk also had two parts. The first was a reminder about normal distributions and standard deviations. If your business asks for a 6% increase in sales in the next 6 months, this is meaningless if the 6% is within the natural variability of the measure. All too often, we forget this, because we just look at the output from a spreadsheet.Francis suggested that we should put the standard deviation on all the graphs we produce for management to highlight this issue.

The second part of the talk described the distinction of ‘efficient’ and ‘effective’: the former is best for a short-term bottom-line but is high-paced and so there is little room for innovation; the latter is more about the long-term, and allows for innovation and experimentation. The final slide contained an interesting note: that we need to be ‘response-able’ for improvements, i.e. that we need the slack time to improve.

 Unlimited resources deliver faster… right? (Alun Worrall)

I always appreciate conference talks where companies feel able to give a ‘warts-and-all’ presentation, owning up to simple mistakes they have made. This was one such talk as Alun described a big project at AutoTrader which involved releasing some software by a critical date. Having estimated that it wouldn’t be possible, the company threw a load of contractors at the problem, hoping that it would speed it up. But the product was still delivered when it was originally estimated, and all that they had achieved was a lot of stress. It also appears that some fundamental mistakes with prioritisation of the individual components of the system could have been done better, which might have helped some of the project to have been delivered earlier.

How I became a spaceship commander (Tomasz Borowski)

Tomasz had tried using the YouTrack system to create YouGame: a gamification of the story-points achieved. This was initially done in response to a particular set of issues, including tasks moving straight from ‘To Do’ to ‘Done’ on the board, and inaccurate estimation. Tomasz described the issues he had faced in various iterations of the game’s development, including the risk of the leaderboard being used for performance bonuses (not the intended use!), and the need to add a concept of ‘stamina’ to prevent people from marking excessive amounts of work as Done.

To me, it sounded very much like an excessive response, and it must have taken a lot of time to create the app, however impressive it is.

The Art of the Retrospective (Chris Smith)

I’ll admit to having seen a practice of this presentation at Red Gate a few weeks ago but this made it even more interesting for me to see the eventual, finished, talk. As someone who hasn’t traditionally done many Sprint retrospectives with my team, I found the number of practical examples in Chris’ talk very useful. I’m certainly looking forward to trying many of them out.


Overall, I thought Agile Camrbidge was excellent, and I hope to be back next year!

Agile Cambridge

Reflections from Agile Cambridge 2013: Day 2

[This post continues from Reflections from Agile Cambridge 2013: Day 1]

Agile Cambridge programme

Change or be changed (Janet Gregory)

Today’s keynote dug down deeper into the concept of how we often can’t avoid change. The presentation was split into three parts: types of change, influences for success and how to introduce change.

The types of change section discussed how we can change a ‘want’ into a need to face change, which often involves seeing opportunity. The change we are driving may have its success determined by other factors, however, including how it was introduced, resistance and whether people feel there is an implicit blame in a culture change. It is therefore necessary to consider any personal agendas people might have. Introducing change involves sharing a vision and involving others, and giving people space to voice any concerns and fears. If the change involves measuring something, it’s also important to explain what we are measuring and why, so they don’t react, thinking they will be punished. [This is something I know that I’m particularly guilty of.]

Scrum & Kanban (Jon Terry)

Unfortunately, this talk had a published title which was different from the one that was presented, entitled ScrumAgiLean, which I had seen previously. The talk is a useful reminder that Scrum and Kanban are complementary, and how they relate to Lean Management. One of the main things I learnt is that we can defer commitment to a particular path by building multiple options at the same time. I wonder how practical it would be to suggest to management that the team should develop something twice in different ways, although I can understand that it can save time in the longer run.

Requirements: whose job are they anyway (Allan Kelly)

This was a disappointing talk in my opinion, as it came across as predominantly being a rant. Perhaps it’s because I’m lucky that at Red Gate we have dedicated Product Managers who talk to customers, but the only really useful thing I took away was a distinction between Product Owner (as an umbrella term), Business Analyst (someone looking at internal users, who are measured by costs) and Product Managers (someone looking at external customers, who are measured by revenue).

Scaling out solutions development with feature teams (Luke Morgan)

This talk was much more useful. Luke started by introducing the ‘Capability Complexity Curve’ to describe how ‘solutions’ different from ‘products’. The majority of his talk, however, focused on the structure of his feature teams, which exist as a subsidiary of a single solution team. For example, he has usability and architecture specialists at the solution (not feature-team) level, to help avoid the issues of Conway’s Law. Another interesting factor was the need to have a DevOps engineer in the feature teams, helping to resolve any infrastructure impediments. The solution team, meanwhile, contains the Release Manager (which is similar to the Project Manager), whilst the ScrumMaster exists at the feature team level.

Open session: DevOps

In an impromptu open session at the end of the day, we discussed the role of DevOps, and in particular whether they should be embedded in the team or separate. The general consensus was that embedded DevOps improves speed and flexibility, whereas separate DevOps teams help get more time for working on infrastructure. Generally, DevOps were seen as being crucial for scalability. Slightly more worryingly, however, the best definition we could come up with was that DevOps are ‘A group to shout at, even though they have no cost centre’.

[This post continues at Reflections from Agile Cambridge 2013: Day 3]

Reflections from Agile Cambridge 2013: Day 1

For the next three days, I’m attending Agile Cambridge at Churchill College, Cambridge. These are my thoughts and notes from the sessions I attended on the first day (Wednesday 25th September).

Keynote: Moving towards symbiotic design (Michael Feathers)

Michael’s talk was one of those which warrants further time to digest. There were lots of individual strands that made sense, but if I were asked to summarise a single conclusion in a take-away tweet-sized sentence, I wouldn’t (currently) be able to.

That’s not to say there wasn’t a lot of good, useful content, however. One of the main strands was about Conway’s Law and the relationship between code and the organisational structure of the teams working on the code. At a simple level, APIs and other interfaces tend to form at the boundaries between different teams but this can result in nobody owning the APIs and so all the teams involved end up doing more work so as to avoid changing the API. An interesting idea presented was that of teams having permeable membranes, the model in which teams in this position share information and, sometimes, people break off into the other team.

Another, related, strand was about Spolsky’s Law of Leaky Abstractions. Agile encourages us to abstract our requirements into Stories, but because this abstraction will be imperfect (will leak), the result will be technical debt. We know this is happening if the developers tell us a feature is big because of some side-effects of decisions that have already been taken. The presenter asserted that Agile development teams rarely communicate back this sort of constraint to the Product Owner, which can lead to the effect Conway described. The metaphor of software engineering being like gardening was introduced: in Waterfall models we may be told to plant something without seeing the garden first. Agile lets us see first whether there are weeds that will choke the plant already present but do we tell anyone about this?

One of the ideas we’ve been thinking of at Red Gate was invoked in a further strand: the idea of ‘internal open source’, whereby any team can contribute to any codebase. While it sounds appealing, the danger is that (without an owner), the product will be trashed just as Common land tends to be spoilt by BBQs and people grazing cows.

What linked these threads was that the Agile manifesto’s assertion of ‘People over process’ is more complex than this. Whilst Michael explicitly stopped short of saying ‘Code over people over process’, the idea of code being king, and considerations of the effects of people on code, underpinned the whole presentation.

Complexity, Governance and the Agile Team (Graham Oakes)

Compared to the keynote, this was far less intellectually challenging but still resulted in some useful learning. The workshop mainly comprised splitting the room by our job titles (Developer, Project Manager, Product Owner, etc.) and asking us to dot vote on who should be responsible for taking a range of decisions. We were then asked to place a number of typical business decisions on the Cynefin complexity model.

The result was surprisingly fascinating: whilst it was a highly unscientific survey, the different roles had ranked the decisions and complexity of the decisions in very different ways. Developers, for example, saw most decisions as coming either from individual team members or from the Project Manager, whilst Product Owners saw most decisions as coming from Senior Management or the whole team – leaving the Project Manager responsible for surprisingly little! Similarly, our job role affected which decisions we saw as simple, complex, etc. quite drastically.

Whilst interesting, I’m not entirely sure what to do with the information, or whether it’s even a problem. If I, as a Project Manager, shield my team from Senior Management’s decision-making, meaning that they see decisions as coming directly from me, can’t that be a good thing?

The rituals of great software engineering teams (Alex Shaw)

Agile Cambridge 2013This was a fascinating talk about the role of ritual in teams, going right back to Confucius (‘Ts’ze, you love the sheep; I love the ceremony‘). The main message was that a key point of ritual can be that the reason for a ritual may be of lesser importance than the ritual itself. There were a few good examples of how the culture of ritual had affected teams, and what can happen to the rituals when the team is upset (for example, by people within the team changing).

Growing eXtreme Programming teams (Rachel Davies)

This was a case study into the way XP is done at Unruly Media. While such insights into other companies are always interesting, there were few original ideas in this. One, however, was the idea of ‘Gold Cards’, whereby team members can opt to spend up to 20% of their time on their own projects on condition that they present back to the team what they spent their time on, if they chose to do this.

We’ve been thinking recently about giving developers some slack time but an enforced 20% for everyone, with potentially little to show for it, seemed likely to work for some people and not for others. This model may be an answer.

We don’t know what we’re doing; let’s go! (Neil Denny)

Probably the best session I attended today and completely relevant to the situation I’m soon likely to find myself in, this was a motivational workshop on dealing with uncertainty as an opportunity for profound change. Although less ‘workshopy’ than I expected, there were some immediately applicable techniques. I couldn’t help thinking, however, that the reality of getting organisational structure to change (if that’s the outcome) was somewhat trivialised.

I’m looking forward to tomorrow…

[This post continues at Reflections from Agile Cambridge 2013: Day 2]